matchedfilter
Batched correlation with a choice of full or peak-only output, on CPU or GPU.
matchedfilter correlates data segments against a template bank and returns the full complex correlation or the strongest sample in each output bin. It accepts complex64 spectra or time-series blocks through run_series().
Documentation · Usage guide · Benchmarks
Alpha software: the API may change. Pin a version for reproducible work.
Quick start
pip install matchedfilterThis example finds a template shifted by 37 samples:
import numpy as np
import matchedfilter as mf

n = 1024
rng = np.random.default_rng(1)
template = rng.standard_normal(n)
data = np.roll(template, 37)

filt = mf.MatchedFilter(n, ndata=1, ntemplates=1)
filt.set_templates(np.fft.fft(template).astype(np.complex64)[None, :])
filt.set_data(np.fft.fft(data).astype(np.complex64)[None, :])
peaks = filt.run(binsize=n)
print(peaks["index"][0, 0, 0])  # 37
The result has shape (ndata, ntemplates, nbins), with index and value fields. value is complex; use abs(value) for its magnitude. Bins below the detection threshold have index == -1 and value == 0. Results may reuse storage: copy any result you need to retain across calls.
See the usage guide for normalization, thresholds, search windows and time-series input.
Use CorrelationFilter when downstream code needs every lag:
full = mf.CorrelationFilter(n, ndata=1, ntemplates=1)
full.set_templates(np.fft.fft(template).astype(np.complex64)[None, :])
full.set_data(np.fft.fft(data).astype(np.complex64)[None, :])
correlation = full.run()  # complex64, shape (1, 1, n); peak at lag 37
It uses the same spectral inputs, bank dimensions, selectors and device choice as MatchedFilter. The full-output mode keeps the fused spectral product and batched transforms, but writes all lags. Peak-only filtering avoids those stores; hierarchical filtering also avoids full transforms for pairs dismissed by its coarse gate.
Supported capabilities
| CPU | GPU | |
|---|---|---|
| Peak-only transform sizes | powers of two, 64–1,048,576 | powers of two, 64–65,536; device limits apply |
| Full-output transform sizes | powers of two, 1,024–4,194,304 | powers of two, 1,024–4,194,304; device limits apply |
| Flat and hierarchical filtering | yes | yes |
Time-series input with run_series() | yes | yes |
| Input spectra and returned values | complex64 | complex64 |
| Execution | one CPU thread | Vulkan or Metal |
Flat filtering and refinement use single precision. GPU hierarchical screening can use reduced-precision kernels. There is no float64 filtering API.
The default device is CPU unless MF_DEVICE is set. Select a GPU explicitly:
print(mf.devices())
gpu_filter = mf.MatchedFilter(4096, device="gpu")
Linux and Windows use Vulkan; macOS uses Metal. A compatible driver is required. Unsupported GPU requests raise an error. See the usage guide for platform and device limits.
Performance
The implementation fuses the frequency-domain product into the inverse transform. Full-output mode writes every lag; peak-only mode scans inside the transform and avoids those writes. Hierarchical mode screens pairs before the full transform. Performance depends on length, bank shape, device and the fraction of pairs requiring refinement.
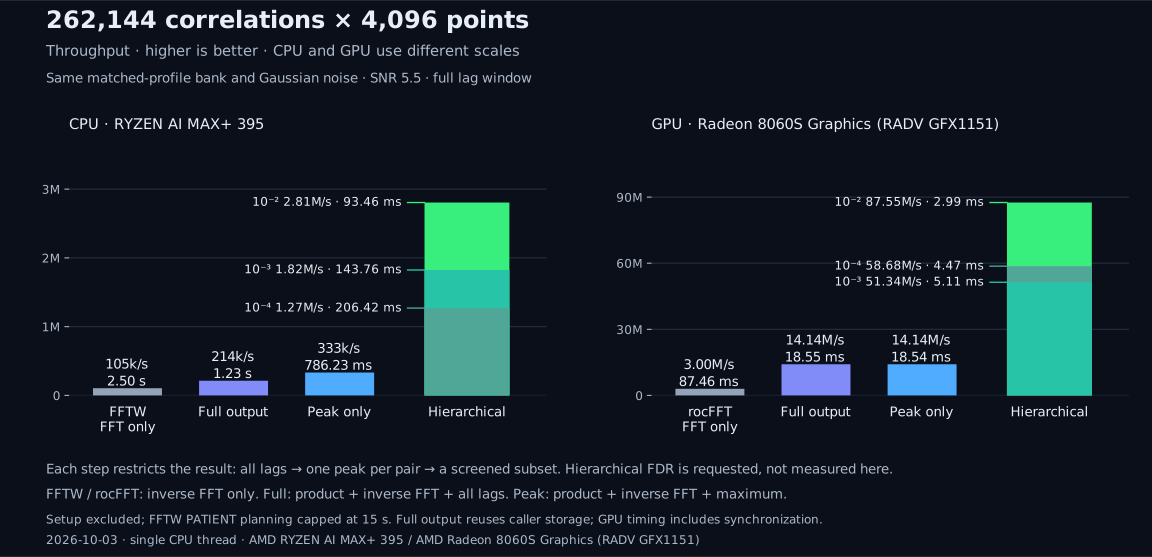
Measured on a Ryzen AI MAX+ 395 / Radeon 8060S: 512 data segments × 512 templates (262,144 pairs), 4,096 points, with the bank drawn from the captured PyCBC reference profile. The bars move from a general inverse FFT to fused full output, peak-only output and hierarchical screening. FFTW and rocFFT time only the inverse transform, so they do less work than the filter bars. Full output reuses a caller-supplied result array; GPU timings include synchronization. Hierarchical bars show requested FDR budgets 1e-2, 1e-3 and 1e-4 at SNR threshold 5.5, with initial autotuning passes settled to empirical best configurations; these noise-only timings do not measure FDR. The two panels use separate scales; compare their printed values. This is a workload example, not a speed guarantee.
For comparisons measured across seven architectures (including 512×512 scaling across NVIDIA L40S, A100, A40, AMD Radeon 8060S, and Apple M2) with selectable thresholds and output modes, see the hardware comparison.
The flat and hierarchical benchmark pages show results across available transform sizes.
Run the benchmarks
python -m pip install pyfftw  # optional FFTW reference
python -m matchedfilter.benchmark --reps 7 --json bench.json
The default sweep covers all 15 CPU sizes, with GPU timings where supported. Batch sizes shrink at large lengths to bound memory use. --n selects a subset. Missing hierarchical calibration is reported explicitly.
To measure warm overlap-save calls, including automatic peak output at 2,048–8,192 points and continuous full output at 32,768 points, run python tools/bench_series_workloads.py. It checks the output before timing and compares automatic layout with explicit blocks. Use --quick for a shorter continuous series; CI records that version on each benchmark host.
Install mkl-fft and mkl for an optional MKL reference where supported. NumPy provides the correctness reference. Without FFTW or MKL, library timings and correctness checks still run. Reference timing covers the inverse FFT; matchedfilter timing also includes the product and peak scan.
Documentation
- Documentation index: current guides, development tools, and research history.
- Usage guide: inputs, normalization, devices and API behavior.
- Examples: noise and injected signals.
- Numerical accuracy: comparison with a float64 reference.
- Design notes: implementation details and historical experiments.